28 March 2022

Why HDX-MS is rare in FBLD – and practical tips to change this

Hydrogen/deuterium exchange mass spectrometry (HDX-MS) can help identify the binding site of a ligand, sometimes. Briefly, a protein-ligand complex is diluted into a solution of D2O; exchangeable hydrogens on the protein will be replaced by deuterium, and those that interact with the ligand will be protected. A comparison with the protein alone will thus reveal which region interacts with the ligand. Practical Fragments discussed the technique back in 2012 and 2014, but since then it has been mentioned only a handful of times. In a new paper in J. Am. Soc. Mass Spectrom. Yoshitomo Hamuro and Stephen Coales (ExSAR) provide insights into why it is rarely used in FBLD, and offer solutions.
 
The researchers argue that the main problem with using HDX-MS in FBLD is that fragments often have low affinities and low solubilities. A theoretical analysis reveals that “the concentration of a ligand, not the molar excess of a ligand over a protein, is the key to drive the equilibrium to complex formation.” A series of calculations with hypothetical ligands having dissociation constants of either 100 µM or 1000 µM reveals that changing the concentration of protein is unlikely to have much effect on the outcome of the experiment, whereas increasing the concentration of ligand will give cleaner data. The problem is that many fragments may not be soluble at sufficiently high concentrations.
 
To solve this challenge, the researchers provide two solutions. First, they suggest spiking ligand into the D2O exchange buffer; this will keep the ligand from being diluted.
 
A second fix is similar: rather than diluting a protein-ligand complex 1:9 into D2O, the researchers suggest a 1:1 dilution, so the ligand concentration drops only by half rather than by 10-fold.
 
High concentrations of ligand can potentially interfere with the mass spectrometry measurements, so the researchers also suggest using smaller volumes with higher concentrations of protein.
 
These all seem like simple, practical measures to make HDX-MS more applicable to FBLD, but unfortunately the paper does not actually provide any experimental proof of concept data, so I’ll put the question to you, dear readers: have you found HDX-MS useful in FBLD? If so, under what conditions?

21 March 2022

Nucleophilic fragments: the other kind of covalent inhibitors

Covalent fragment-based lead discovery is becoming increasingly popular, spurred on by the rapid discovery and approval of sotorasib. In general, covalent inhibitors contain cysteine-reactive electrophiles, though efforts are also targeting other amino acid residues such as serine and lysine. In all these cases though, the fragment contains an electrophile, while the protein contains the nucleophile. A new paper in J. Am. Chem. Soc. by Megan Matthews and collaborators at University of Pennsylvania and Oberlin College turns things around.
 
None of the twenty standard amino acids are electrophilic, but some proteins do use electrophilic cofactors, such as pyridoxal phosphate. Moreover, some proteins undergo post-translational modifications which introduce a pyruvoyl (Pyvl) or glyoxylyl (Glox) group onto the N-terminus; these contain, respectively, an electrophilic ketone or aldehyde. As we wrote about here, aldehydes and ketones can react covalently with hydrazines, and the new paper shows that the kinetics of this reaction vary – as expected – with the nucleophilicity of the hydrazine.
 
Next, the researchers assembled a library of 17 fragment probes containing both a nucleophile as well as an alkyne that could be used for click chemistry. These probes were screened against cells for 30 minutes at 37 °C, the cells were lysed, labeled proteins conjugated to a dye, and the whole gemish run on a denaturing gel; the results showed a wide range of reactivities for the different probes.
 
To assess which proteins were reacting with which probes, the researchers turned to isoTOP-ABPP, a chemoproteomic method we previously wrote about here in the context of electrophilic fragments. (Chemical biologists are fond of abbreviations, and they call this new approach with nucleophilic fragments “reverse-polarity activity-based protein profiling”, or RP-ABPP.) Three probes, P11, P12, and P13, were found to modify 98, 60, and 16 proteins, respectively. Remarkably, despite their small size and common hydrazine nucleophile, only a single protein was labeled by all three probes.
 

Two of the proteins labeled by P11 include secernin-2 and -3 (SCRN2 and SCRN3). The functions of these proteins are unknown, though genome-wide studies have associated SCRN3 with several diseases.
 
The requirement for the probes to contain both an alkyne handle and a nucleophile increases complexity, and the researchers recognized that they could use the probes in competition mode against fragments lacking the alkyne. They assembled a set of 45 nucleophile-containing fragments and treated cell lysates with these, followed by treatment with probe P11, click chemistry to introduce a fluorescent dye, and gel electrophoresis. Hydrazine-containing fragments that inhibited the binding of P11 were found for SCRN2, SCRN3, and the protein AMD1. Some of these fragments showed EC50 values less than 1 µM and were up to 25-fold selective for SCRN3 over SCRN2 despite the 54% sequence identity shared between the two proteins.
 
An orthodox medicinal chemist might sniff at the hydrazine moiety in these molecules, but it is worth noting that P12, P13, and P17 are all derived from approved drugs (carbidopa, hydralazine, and phenelzine; substructures colored blue).
 
The functional roles of Pyvl and Glox modifications in proteins are poorly understood, and whether modulating them will prove useful in treating diseases remains uncertain. But the best way to answer this question will be by inventing suitable chemical probes. This paper suggests that nucleophilic fragments may prove useful.

14 March 2022

Higher hit rates with heavier halogens

Halogen bonding is an esoteric type of molecular interaction. Any first-year chemistry student can tell you that halogens are electronegative. More advanced students learn that the electron density on a halogen attached to a carbon is not evenly distributed. Rather, an electron deficient region appears directly opposite the carbon bond on chlorine, bromine, and iodine atoms. This “σ-hole” can form attractive interactions with electron-rich moieties, such as backbone carbonyl atoms. These highly directional interactions can be useful alternatives to hydrogen bonds, especially since they allow a reduction in the number of hydrogen bond donors. But how to find them? This is the topic of a recent open-access paper in Frontiers in Chemistry by Frank Boeckler and collaborators at Eberhard Karls Universität Tübingen.
 
The researchers constructed a library of 191 commercially available halogen-enriched fragments (called HEFLibs), which we wrote about in 2019. Most fragments have a single halogen atom, though 15 have two of the same type (two chlorine atoms, for example). The initial publication had no screening data, but the new paper describes screening the library against four diverse proteins: the methyltransferase DOT1L, the oxygenase IDO1, and the kinases AAK1 and CAMK1G.
 
Ligand-detected STD NMR was used as the primary screen, with proteins present at 20 µM and fragments at 1 mM each in mixtures of two. Between 9 and 57 hits were found for each target, with unique hits for all the targets except DOT1L. Some fragments hit all four targets, including one similar to the "universal fragment" we highlighted here.
 
Interestingly, iodine-containing fragments gave higher hit rates than bromine-containing fragments, which in turn gave higher hit rates than chlorine-containing fragments. Specifically, 9 of 14 (64%) iodine-containing fragments hit at least one target, vs 51% and 35% for bromine- and chlorine-containing fragments.
 
To assess whether halogen bonding played a role, the researchers calculated maximum electrostatic potential (Vmax) for each fragment; this is a measure of the size of the σ-hole. Fragment hits tended to have higher Vmax values than non-hits.
 
One possible confounding influence is that aryl halides can react with cysteine residues in proteins, and indeed the researchers did find that some of their fragments are unstable in the presence of the cellular reducing agent glutathione.
 
To confirm the STD-NMR results with an orthogonal method, the researchers turned to isothermal titration calorimetry (ITC). Of 57 fragment-protein pairs tested, only ten gave KD values less than 1 mM, and nine were against the kinases; there were even a couple single-digit micromolar binders for AAK1. ITC is less sensitive than NMR, so some of the other fragments may bind too weakly to fully characterize.
 
Unfortunately, crystallography has been unsuccessful so far, so it remains unclear whether any of the hits are actually making halogen bonding interactions with the proteins. Halogens are good at filling lipophilic pockets, so it is perhaps likely that less specific van der Waals interactions are the key affinity drivers. But the Boeckler group has been pursuing halogen bonding for more than a decade, so I look forward to seeing more on this topic.
 
And in the meantime, happy Pi Day!

07 March 2022

Virtual screening succeeds against the SARS-CoV-2 main protease

Today marks exactly two years since Practical Fragments first mentioned SARS-CoV-2. Since then, COVID-19 has killed more than 6 million people worldwide. Multiple effective vaccines have been developed and approved, along with a couple small-molecule drugs, but the virus is here to stay, and more drugs will be needed. This brings us to an open-access paper published in J. Am. Chem. Soc. by Jens Carlsson (Uppsala University) and a large group of international collaborators.
 
The so-called main protease (Mpro, or 3CLp) has been an antiviral target since the earliest days of the pandemic; the work we highlighted two years ago focused on a crystallographic screen against this enzyme. The new paper describes two virtual screening approaches.
 
The first started with a library of 235 million virtual compounds, mostly from Enamine’s “readily available for synthesis” (REAL) collection. Each compound was docked in thousands of different orientations against the active site of Mpro using DOCK3.7. Despite the staggering numbers (more than 223 trillion complexes!), the screen took just a day on 3500 CPU cores. The top 300,000 compounds were clustered based on similarity, and 100 molecules were synthesized. Nineteen of these showed binding by SPR, and three also inhibited the enzyme. Crystal structures were obtained for two of these, and both bound similarly to the predicted binding modes.
 
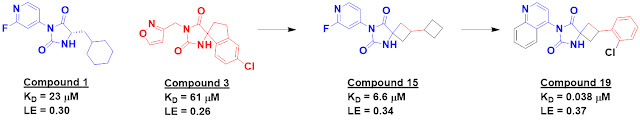
Compounds 1 and 3 each contain a hydantoin moiety that makes multiple hydrogen bonds to the protein, and merging elements led to low micromolar compounds such as compound 15. Further optimization ultimately delivered compound 19.
 

Compound 19 was potent in SPR and biochemical assays. Though it binds noncovalently, it had comparable cellular activity to nirmatrelvir, the recently approved covalent inhibitor of Mpro. Compound 19 showed nanomolar cell potency against SARS-CoV-1 and MERS-CoV and good selectivity against ten human proteases. The in vitro stability and permeability of compound 19 are also promising.
 
In addition to this de novo virtual screen, the researchers performed a second screen starting from one of the fragments identified crystallographically at Diamond Light Source. Of 93 molecules purchased and experimentally tested, 21 showed binding by SPR and 5 of these also inhibited the enzyme, with the most potent compound showing low micromolar activity.
 
There are several lessons from this paper. First, despite searching hundreds of millions of compounds, the best hits had only modest activity. This is perhaps surprising given the high fragment hit rates observed against Mpro in crystallographic and NMR screens, though it is worth noting that those fragments were even weaker binders.
 
Second, the hit rate from the naïve virtual screen was similar to that from the experimentally derived fragment screen. The researchers suggest that perhaps docking “may be more proficient in ranking diverse chemotypes rather than differentiating between closely related elaborations of the same scaffold.” In other words, virtual screens seem better at evaluating diverse starting points rather many similar molecules.
 
Third, despite the fact that the de novo virtual screen was not explicitly fragment-based, compound 1 does actually adhere to the rule of three. From there, addition of just six atoms improved affinity by >600-fold while also improving ligand efficiency.
 
Finally, this work is a testament to the utility of combining massive virtual screening with readily synthesizable compounds: the researchers note that it took less than four months to progress from compound 1 to nanomolar inhibitors.
 
This work relied heavily on rapid chemical synthesis done in Ukraine. Indeed, the two most popular fragment suppliers are both largely based in that country. Over the years many of us have come to know Ukrainian scientists not just as trusted colleagues but also as friends. I wish them and their families safety, and strength.

28 February 2022

Photoaffinity fragment PhABits, faster

Practical Fragments has written previously about PhotoAffinity Bits, or PhABits, which are fragments designed to reveal binding (as opposed to inhibition). These fragments contain a photoreactive moiety such as a diazirine. When incubated with a protein target and irradiated by ultraviolet light, the diazirine transforms into reactive species that can react irreversibly with anything nearby. Intact protein mass spectrometry can identify whether a reaction has occurred, and further proteomics experiments can identify more precisely where the PhABits reacted.
 
One challenge with this approach is obtaining a library of PhABits; few are commercially available (though AstraZeneca is sharing a set). In a recent open-access Chem. Sci. paper, Jacob Bush and collaborators at GlaxoSmithKline and University of Strathclyde describe speeding up the process.
 
The approach is called direct-to-biology high-throughput chemistry (D2B-HTC). Recognizing that purification is often the rate-limiting step in library synthesis, the researchers synthesized PhABits in 384-well plates and used the crude reaction mixtures directly. In short, a diazirine moiety linked to an activated ester was reacted for 24 hours with 1073 diverse alkylamines chosen from the GlaxoSmithKline internal collection. Interestingly, 54 of the amines themselves were not pure as judged by LC-MS – a useful reminder of the importance of quality control. Ultimately, 853 of the reactions were deemed successful, with >80% purity. Residual activated ester was quenched with hydroxylamine, and the reactions were performed in biologically compatible DMSO so that they could be used directly.
 
Next, each member of the library was screened at 100 µM against human carbonic anhydrase I (CAI, at 1 µM), a well-characterized model protein. After UV light illumination (302 nm for 10 minutes) the reactions were analyzed by mass spectrometry, resulting in seven hits, defined as > 1.5% covalent adduct. Five of these contained a primary sulfonamide, a privileged pharmacophore for carbonic anhydrases. Dose response experiments gave similar results on both the crude mixtures as well as resynthesized, pure compounds, with the best molecule showing high nanomolar activity. All seven PhABits could be competed with the known ligand ethoxzolamide, suggesting that they bind in the active site of the enzyme.
 
The seven hits gave even higher levels of modification with carbonic anhydrase II (CAII), and four of the sulfonamide-containing hits were further characterized by proteolyzing the modified enzyme and using LC-MS/MS to determine the sites of modification. This revealed that the PhABits were reacting with either a glutamic acid or histidine residue at the entrance of the active site. As we discussed last year, the precise nature of the diazirine probe can affect which amino acid residues are likely to react.
 
Based on the SAR from the primary screen, a second 100-member library was constructed and screened without purification. This provided a much higher hit rate, with all 52 hits containing a primary sulfonamide.
 
I do wish the researchers had used an orthogonal method to assess the affinities of their molecules. One drawback of the approach, which they note, is that “the absolute value of the crosslinking yield is not indicative of binding affinity,” but it would be interesting to know whether there is any correlation at all. It would also be nice to get a sense of how often false negatives occur.
 
Still, D2B-HTC adds to the growing list of methods that screen crude reaction mixtures, alongside related approaches such as off-rate screening, Chemotype Evolution, and REFiLx. The future may be a bit dirty, but perhaps we can get to our destination faster.

21 February 2022

Ensembles of fragment structures guide selectivity

Scientists generally want structural information when a project begins, and ideally that structural information comes from crystallography. Most of us who have been doing drug discovery for a while can remember seeing the first structure of a favorite molecule bound to a target protein and being inspired, reassured, or sometimes confused. But as crystallography becomes increasingly high throughput, it is now not uncommon to obtain dozens or even hundreds of structures. What to do with all this bounty? In a recent open-access J. Chem. Inf. Model. paper, Mihaela Smilova, Brian Marsden, and collaborators at University of Oxford, the Cambridge Crystallographic Data Centre, and Exscientia describe one application.
 
Back in 2016 we wrote about a computational approach called hotspot mapping, which uses three small fragment probes (aniline, cyclohexa-2,5-dien-1-one, and toluene) to virtually explore potential binding sites and map hydrogen bond acceptors, donors, and apolar interactions. The idea was to predict binding sites and the key interactions likely to drive affinity. The new paper focuses not just on affinity, but on selectivity.
 
The approach starts by taking multiple structures of the same protein bound to various ligands, especially fragments. Ligands and water molecules are then removed, and hotspot mapping is conducted for each structure. Then, all the hotspot maps are combined to generate an “ensemble” hotspot map, which in theory should give a more complete picture of potential attractive and repulsive interactions than a single structure.
 
To assess selectivity, the ensemble hotspot map of one protein is “subtracted” from that of another. If the proteins are very closely related, this “selectivity map” might be empty: all the interactions for one protein would be present in the other. But if there are differences, they become very apparent.
 
Several retrospective case studies are provided. In the first, ensemble hotspot maps were generated from the closely related bromodomains BRD1 and BRPF1, using 23 and 26 fragment-bound structures, respectively. The selectivity map clearly shows the potential for a hydrogen bond donor on a ligand to bind to the backbone amide of a serine in BRD1; the corresponding residue in BRPF1 is a proline, incapable of making this interaction. And indeed, an examination of the literature revealed that this interaction had previously been used to generate inhibitors of BRD1 that were 15-fold selective over BRPF1.
 
The kinases p38α and ERK2 are also closely related, but selectivity maps generated from five p38α structures and 17 ERK2 structures revealed a hydrophobic pocket in the former but not in the latter. This pocket had previously been used to generate selective inhibitors of p38α. Similarly, 28 structures of CK2α and 32 structures of PIM1 were used to generate a selectivity map that also revealed a hydrophobic pocket that can form in the former protein and had been used to generate selective inhibitors.
 
Generally, the more structures available, the more informative the selectivity maps are. The researchers note that though they only used five p38α structures, the fragments were chosen to be diverse (and interestingly all of them made interactions in the hydrophobic pocket). Also, while some protein flexibility can improve the maps, too much is a problem. (For the kinases, only DFG-in structures were used, for example.)
 
This method is a nice synthesis of experimental and computational techniques. A skeptic might argue that it doesn’t provide fundamentally new information: in the examples provided, the selectivity features had already been found and exploited by medicinal chemists. But the automated process and the clear output may speed things up, especially for newer targets, and indeed the researchers note that it is being applied in-house at Exscientia.
 
Perhaps most importantly, if you’d like to try it yourself, the code is freely available here. Happy mapping!

14 February 2022

Fragment merging vs bacterial SAICAR synthetase

People living with cystic fibrosis are susceptible to lung infections from a rogues’ gallery of bacterial species, one of which is Mycobacterium abscessus. It is often antibiotic resistant, and even when it responds, a course of antibiotics can take two years to resolve the infection. In a recent ACS Infect. Dis. paper Tom Blundell, Anthony Coyne, and collaborators at University of Cambridge and elsewhere describe progress against this organism.
 
The researchers chose to target a protein called SAICAR synthetase, or PurC, which is essential for purine biosynthesis and thus bacterial growth, as shown by genetic knockout studies. The enzyme is significantly different from the human ortholog, but similar to the Mycobacterium tuberculosis ortholog, giving the potential for a twofer.
 
Fragment screening was conducted both in-house using thermal shift assays as well as at XChem using crystallography; we discussed the differing outputs of these screens in this 2019 post. Compound 1, from the in-house screen, was found crystallographically to bind in the ATP-binding site, and ITC studies revealed it to have high micromolar affinity for the protein. Meanwhile, compound 2 was identified from the crystallographic screen, and while the affinity wasn’t measured, the pyridyl ring is located a short distance from where compound 1 binds.


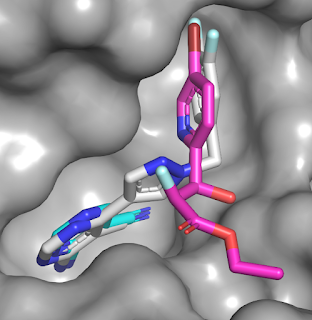
Initial SAR around fragment 1 revealed that growing toward the binding site of compound 2 would be possible, as illustrated by compound 9. Appending a pyridyl ring onto this molecule led to compound 16, with low micromolar affinity. The pyridyl moiety stacks onto an arginine side chain, and improving this interaction by replacing the pyridyl with a phenyl appended with electron-withdrawing fluorine atoms led to compound 27, with submicromolar activity. Overlaying the crystal structures of compounds 1 (cyan), 2 (magenta), and 27 (gray) reveals that the merged molecule does indeed bind in a similar manner to the component fragments.

Unfortunately, despite good biochemical activity against PurC, none of the compounds were particularly effective at inhibiting growth of either M. abscessus or M. tuberculosis. Such disconnects between biochemical and cell potency are unfortunately all too common, particularly for antimicrobial targets, as we wrote about here. The researchers suggest possible reasons including efflux and physicochemical properties. The paper ends by noting that work is continuing, and we look forward to hearing more.

07 February 2022

Automated scaffold hopping for fragments

A post last month covered high-throughput virtual screening, but most practitioners of FBLD still start with some sort of (bio)physical screen. These initial hits can’t be expected to be optimal, since the average fragment library contains a few thousand compounds at most. Indeed, as Xavier Barril and collaborators at Universitat de Barcelona and Oxford University write, “fragment hits should be seen as beacons indicating privileged areas of chemical space to be further explored.” They describe one way to expedite exploration in a recent J. Med. Chem. paper.
 
As we noted here, most good fragments make at least one essential interaction (such as a hydrogen bond) to the protein. The approach starts with a structure of a fragment bound to the target of interest, with that essential interaction identified.
 
Next, a virtual library is searched for similar molecules, with the definition of “similar” being rather loose (>50% Tanimoto similarity). Ideally the library is large enough to produce lots of hits; the researchers used ZINC15, which contains >15 million ostensibly commercial compounds. Also, only molecules within two non-hydrogen atoms of the starting fragment are considered. In other words, a fragment with ten “heavy” atoms would yield molecules with 8-12 non-hydrogen atoms. This search is similar though perhaps more permissive than Astex’s Fragment Network (which we wrote about here).
 
All the molecules are then superposed on the initial fragment structure and only those that maintain the key interaction and binding mode are kept. Aboout 500 molecules are then selected to represent the best and most-diverse hits. These are subjected to dynamic undocking (DUck), which weeds out fragments that have weaker interactions. If desired, each of the remaining hits can be subjected to further cycles.
 
To demonstrate the approach, the researchers turned to bromodomains, a popular target class for FBLD. They started with 1XA, a fragment Teddy highlighted back in 2013 that led to a clinical compound against BRD4. The isoxazole moiety makes a hydrogen bond with the side chain nitrogen of an asparagine that normally binds to acetylated lysine residues. After one cycle, 58 molecules were selected, but unfortunately only five were actually available commercially. Compound 3 had similar affinity and ligand efficiency as 1XA, and this scaffold had not been reported as a bromodomain ligand. A crystal structure of compound 3 bound to the first bromodomain of BRD4 confirmed the predicted binding mode.

Three additional successive iterations were conducted to look for more ligands, but experimental confirmation was challenging as overall only 17 of more than 100 ligands selected for purchase were commercially available. (Compound 23 was chosen for custom synthesis as it was related to a family of high-scoring molecules.) Encouragingly, eight molecules were active in a differential scanning fluorimetry (DSF) assay, a technique that works well for BRD4. Crystal structures of two of these were obtained: compound 9 contains an isoxazole moiety like 1XA (and indeed resembles this fragment) but compound 23 is quite distinct.


Overall this looks like a valuable method for scaffold hopping. Not only might the described approach lead to novel molecules, it could provide new growth vectors that may not be accessible from the original fragment. Before jumping immediately into chemistry with your fragment hits, it may be worth trying something like this.

31 January 2022

A framework for evaluating commercial fragment libraries

The easiest way to build a fragment library is to purchase one. Quite a few vendors sell fragments, and as our poll from a few years ago demonstrated, most buyers are quite happy with them. But what exactly do they offer? This is the subject of a new paper by Gilles Marcou, Esther Kellenberger, and colleagues at CNRS Université de Strasbourg in RSC Med. Chem.
 
The researchers analyzed 86 different libraries from 14 vendors that were available in February of 2021. These were classified into ten categories, such as “general,” “3D-shaped,” “metal chelating,” “diverse,” “covalent,” etc. Individual library sizes ranged considerably: 41 had ≤ 2000 compounds, 31 had 2000-10,000, and 14 libraries had > 10,000 molecules. The total number of fragments came to 754,646, of which 512,284 were unique, indicating some redundancy between libraries. Laudably, the structures and several analyses are all provided as downloadable files here.
 
Most of the fragments are 200-300 Da, with only 13% less than 200 Da. This skew towards larger molecules is common but may not be desirable, as researchers at Astex demonstrated back in 2014. On the other hand, people do seem to be paying attention to lipophilicity: nearly half the fragments have AlogP < 1. Interestingly, less than a quarter of fragments strictly fulfill the rule of three, though the majority of violations are for more than 3 hydrogen bond acceptors, which is probably not as important as the other criteria, according to analyses of approved drugs.
 
Two different methods were used to assess diversity. These were applied to 433,433 compounds from fifty libraries; specialized libraries such as fluorine-rich and covalent libraries were excluded. The first analysis deconstructed fragments into 59,270 component scaffolds. Not surprisingly, benzene was the most common, present in nearly 5% of all fragments. Quinoline, indole, pyridine, and benzimidazole all were present in at least 1% of compounds. At the other end of the spectrum, 36,555 scaffolds occurred only once. Not surprisingly, these tended to be more complex.
 
In addition to assessing scaffolds, the researchers developed a “Generative Topographical Map (GTM) model to represent the chemical space in a landscape.” The resulting figures do indeed look like topographical maps, with darker regions corresponding to more populated areas. For example, since substituted benzimidazoles are common and similar to one another, they form a dark cluster. Not unexpectedly, the landscape for the set of 433,433 compounds is heterogenous, with denser regions separated by sparsely-populated regions.
 
A nice feature of the GTM model is that it allows easy, intuitive comparisons. For example, some of the “diverse” libraries are more diverse than others, or emphasize different regions of chemical space, and potential customers may want to take these into account.
 
Fragment shapeliness was assessed using plane of best fit (PBF), where lower values correspond to “flatter” molecules, such as benzene, with PBF = 0. The libraries varied considerably in their average PBF, though reassuringly the “3D-shaped” libraries did have higher values. Interestingly, GTM models showed both flat (PBF < 0.1) and non-planar (PBF ≥ 0.1) fragments had similar distributions across fragment space.
 
Overall this is a valuable snapshot of the current state of commercial libraries, and makes a useful complement to the ongoing analysis Chris Swain does at Cambridge MedChem Consulting. Of course, the devil is in the details; PAINS still sometimes show up in commercial libraries, and quality control can vary. In the end you’ll want to do your own vetting, but this is a good place to start.

23 January 2022

Fragments (almost) in the clinic: MRTX1719

Synthetic lethality is a relatively new approach to cancer therapy. The idea is to inhibit a protein that is necessary for cancer cells but dispensable for normal cells, thereby minimizing toxicity. Last year we described one example, and in a just-published open access J. Med. Chem. paper Chris Smith and colleagues at Mirati describe another.
 
The biology gets a bit complicated, so please bear with me. Protein arginine methyl transferase 5 (PRMT5) is an epigenetic writer that adds two methyl groups to arginine residues in a wide variety of proteins. It is essential for cell survival. PRMT5 uses a cofactor, S-adenosyl-L-methionine (SAM), that is converted to methylthioadenosine (MTA) during the reaction. In certain cancers a gene called methylthioadenosine phosphorylase (MTAP) is deleted, causing an accumulation of MTA and – through product inhibition – a decrease in PRMT5 activity. The idea is to develop a drug that binds to and further stabilizes the (inactive) PRMT5•MTA complex, which is abundant in cancer cells, while not interfering with the active form of the protein, which predominates in normal cells. Told you it was complicated! [Note added: as befits the complicated biology I got a couple things wrong, corrected in the comment on 26 Jan.]
 
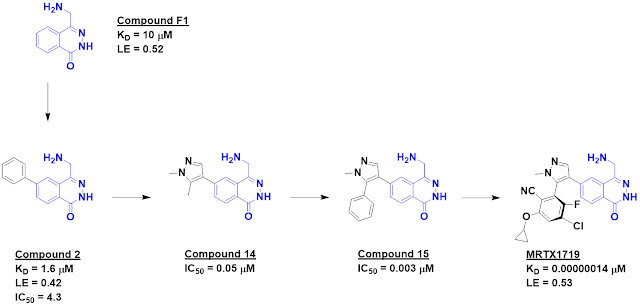
The researchers started with an SPR screen of 1000 commercially available fragments, each at 100 µM. PRMT5 was immobilized on the chip, with MTA added to the buffer to form the PRMT5•MTA complex. This screen yielded 17 hits, and based on this encouraging result a further set of nearly 1900 fragments was screened at 500 µM. The higher concentration yielded significantly more hits, and when these were tested in dose response experiments 100 were found with dissociation constants better than 1 mM. The best 24 of these were then screened against PRMT5 loaded with either MTA or the cofactor SAM. Compound F1 proved to be 5-fold selective for the MTA-bound protein over the SAM-bound protein.
 
Crystallography revealed that this molecule binds in the substrate-binding site in the vicinity of MTA and suggested that it would clash with SAM binding, thus providing an explanation for its selectivity. The crystal structure also revealed a nearby pocket that could be targeted through fragment growing, and this was accomplished with compound 2, which also showed activity in a biochemical assay. Further structure-based design led eventually to compound 14, which was 26-fold selective for the MTA-bound protein.
 

Crystallography revealed another lipophilic pocket, and adding a phenyl group provided a nice increase in potency in the form of compound 15. This molecule also showed low micromolar cell activity. Further structure-based drug design ultimately led to MRTX1719; the medicinal chemistry is elegant but beyond the scope of this post. Chemists will recognize that the final molecule is an atropisomer. This type of stereoisomer is uncommon in drugs in part because they can be difficult to separate; the researchers note assessing 70 different conditions before abandoning one series in favor of a more tractable one.
 
The dissociation constant of MRTX1719 was measured by SPR as 0.14 pM and 9.4 pM for the PRMT5•MTA and PRMT5•SAM complexes, respectively. We don’t encounter femtomolar binders very often; the dissociation half-life for the MTA-bound protein is 14 days! The 67-fold difference in binding was in good agreement with 70-80-fold differences in cells without or with MTAP.
 
MRTX1719 was quite selective in a panel of 42 methyltransferases. Pharmacokinetics and oral bioavailability were good in mice, dogs, and cynomolgus monkeys. The molecule was well tolerated in a mouse tumor model and caused tumor growth inhibition. Based on these results, an IND for the molecule has been submitted to the FDA.
 
This is a lovely fragment-to-candidate story, and Practical Fragments wishes everyone involved good fortune in the clinic!

17 January 2022

An epidemic of aggregators, and suggestions for cures

COVID-19 has been with us for over two years now. While the human effects have been unquestionably negative, for science it has been the best of times and the worst of times. The development of remarkably effective vaccines in less than a year stands as a triumph of twenty-first century medicine, as does the discovery of nirmatrelvir, a covalent inhibitor of the SARS-CoV-2 main protease Mpro (also called 3CL-Pro). But there is a lot of junk-science out there too, as illuminated in a recent J. Med. Chem. paper by Brian Shoichet and colleagues at University of California San Francisco.
 
Before vaccines and custom-built drugs were developed, labs everywhere started screening all the compounds they could get against targets relevant for COVID-19. The most popular molecules to test were approved drugs, the idea being that if any of these turned out to be effective they could immediately be put to use.
 
One of the most common artifacts in screening is caused by aggregation: small molecules can form colloids that non-specifically inhibit a variety of different assays. This phenomenon has been understood for more than two decades; Practical Fragments wrote about it back in 2009. Unfortunately, many labs ignore it.
 
The UCSF lab investigated 56 drugs that had been reported in 12 papers as inhibitors against two targets relevant for SARS-CoV-2, including 3CL-Pro. The molecules were characterized in multiple assays: particle formation and clean autocorrelation curves in dynamic light scattering (DLS), inhibition of an aggregation-sensitive enzyme in the absence of detergent but no inhibition in the presence of detergent, and a high Hill slope in the dose-response curve. Nineteen molecules, four of them fragment-sized, were positive in most of these assays, clearly indicating aggregation. (Interestingly, several of these gave reasonable Hill slopes (<1.4), and the researchers suggest this be a “soft criterion.”) Another 14 molecules gave more ambiguous results, such as forming particles by DLS but not inhibiting the sentinel enzyme.
 
OK, so maybe the molecules are aggregators, but perhaps they also act legitimately? Unfortunately, of the 12 drugs reported in the literature to inhibit 3CL-Pro, only two inhibited the enzyme in the presence of detergent, and one of these was five-fold less potent than reported. And as the researchers point out, detergent is not a magic elixir, and sometimes only right-shifts the onset of aggregation. Moreover, of the 19 molecules conclusively found to be aggregators, detergent was not included for 15 of them in the original publications. Brian may be too polite to write this, but channeling my inner Teddy, I would argue that the authors are negligent for failing to test for aggregation, as are the editors and reviewers who allowed these papers to be published.
 
And the problem is not confined to the COVID-19 literature. The researchers examined a commercial library of 2336 FDA-approved drugs, 73 of which are known aggregators. Another 356 were flagged in the very useful Aggregation Advisor tool (see here), and 6 of 15 experimentally evaluated tested positive in all the aggregation assays.
 
How do you avoid being misled by these artifacts? An extensive suite of tools for assessing aggregation is provided in a recent Nat. Protoc. paper by Steven LaPlante and colleagues at Université du Québec and NMX. The procedures are described in sufficient detail that they “can be easily performed by graduate students and even undergraduate students.”
 
Most of the focus is on various NMR techniques, such as one we wrote about here. The easiest is an NMR dilution assay, in which a 20 mM solution of a compound in DMSO is serially diluted into aqueous buffer at concentrations from 200 to 12 µM. If the number, shape, shift, or intensities of the NMR resonances changes, aggregation is likely.
 
Another assay involves testing compounds in the absence and presence of various detergents, including NP40, Triton, SDS, CHAPS, Tween 20, and Tween 80. Again, changes in the NMR spectra suggest aggregation.
 
The researchers note that “no one technique can detect all the types of aggregates that exist; thus, a combination of strategies is necessary.” Indeed, the various techniques can distinguish different types of aggregates which can vary in size and polydispersity. On a lemons-to-lemonade note, these “nano-entities” might even be useful for “drug delivery, anti-aggregates, cell penetrators and bioavailability enhancers.”
 
We live in the age of wisdom and the age of foolishness. As scientists – and as people – it is our responsibility to aspire to the former by being aware of “unknown knowns,” such as aggregation. And perhaps, by even taking advantage of the weird phenomena that can occur with small molecules in water.

10 January 2022

Virtually screening 11 billion compounds – no problem!

Three years ago we highlighted virtual screens of roughly 100 million molecules which led to numerous high-affinity ligands against two targets. Those efforts made use of the Enamine “readily available for synthesis” (REAL) library, a virtual catalog of molecules that can be rapidly made and delivered. Enamine is continuing to grow this resource, which as of last year stood at 11 billion compounds. This is an impressive number, but how do you make use of it? In a just-published paper in Nature, Vsevolod Katritch (University of Southern California, Los Angeles) and a large group of collaborators provide a promising fragment-based solution.
 
Molecules in the Enamine REAL collection can be made using one-pot parallel synthesis from two or three reagents; for example, an amide could be made from an amine and a carboxylic acid. Enamine built a set of 75,000 reagents and 121 different reactions which collectively could produce 11 billion molecules (it’s even larger now). However, docking all of these could take thousands of years on a single CPU or cost hundreds of thousands of dollars on a computing cloud.
 
Rather than docking all the Enamine REAL compounds, the researchers developed an approach called virtual synthon hierarchical enumeration screening, or V-SYNTHES. The first step is to create a library of scaffolds with molecular weights in the 250-350 Da range. Taking the amide example above, imagine linking a set of 1000 amines to benzoic acid and a set of 1000 carboxylic acids to methylamine. This 2000 compound minimal enumeration library, or MEL, could be considered a subset of the full 1000 x 1000 = 1,000,000 virtual amide library. The numbers are even more dramatic for a three-component reaction: a MEL of just 1500 compounds could represent 125,000,000 fully elaborated molecules.
 
The MEL is docked against a protein of interest, and a diverse set of the top-scoring compounds chosen for fragment growing. In our example, the benzoic acid “cap” on the best compounds would be replaced by the full set of 1000 carboxylic acids. These would then be virtually screened, and the top compounds synthesized and tested.
 
The researchers applied V-SYNTHES to two targets. The first was a cannabinoid receptor bound to an antagonist. A total of 1.5 million molecules were docked against CB2, representing 11 billion fully enumerated compounds. After filtering the best hits to remove PAINS and molecules similar to known CB2 ligands, 80 diverse compounds were chosen for actual synthesis and testing, of which Enamine was able to deliver 60 in less than 5 weeks. One-third of these turned out to be antagonists with Ki values < 10 µM in biological assays.
 
How does this compare to a brute-force approach? Screening all 11 billion molecules wasn’t feasible, so the researchers screened a representative subset of the Enamine REAL library consisting of 115 million molecules – two orders of magnitude larger than the libraries screened in V-SYNTHES. Of 97 compounds synthesized and tested, only 5 turned out to be antagonists of CB2 with Ki values < 10 µM.
 
A nice feature of V-SYNTHES is that it is well-suited to SAR-by-catalog. This was demonstrated by looking for analogs of the three best hits within Enamine REAL space. Of 104 compounds synthesized and tested, more than half had Ki values < 10 µM, and 23 were submicromolar antagonists. In fact, several turned out to be low nanomolar and selective not just against the related CB1 receptor but against a panel of 300 other GPCRs.
 
V-SYNTHES was also applied to the kinase ROCK1 and achieved similarly impressive results: six of 21 compounds synthesized and tested had Kd < 10 µM in a binding assay, and one was a low nanomolar inhibitor.
 
This is a lovely and practical application of fragment concepts. Importantly, because the computational cost only increases linearly with the number of synthetic components while the library size increases with the square (for two-component molecules), it is very scalable; the researchers suggest that “terascale and petascale libraries” should be “easily” accommodated. These are numbers beyond even what DNA-encoded libraries can promise.
 
Currently V-SYNTHES relies on a good structural model for docking, but as computational predictions of protein structures become ever more accurate, perhaps even this will cease to be a limitation. Our SkyFragNet post from 2019 is looking ever more prophetic, in a good way.

05 January 2022

Fragment events in 2022

Will 2022 mark the full return of in-person conferences? That's the plan - here's hoping SARS-CoV-2 doesn't interfere.

February 5-9: The  SLAS2022 International Conference and Exhibition will be held in Boston, so if you're looking for new instrumentation this is the place to be.

March 20-24: The American Chemical Society will hold its Spring National Meeting both in-person and virtually in San Diego. There are bound to be fragment talks, including a session on Modern Screening Methods on March 24.

March 27-29: The Royal Society of Chemistry's Fragments 2022 will be held in the original Cambridge, and also virtually. This is the eighth in an esteemed conference series that historically has alternated years with the FBLD meetings. You can read my impressions of Fragments 2013 and Fragments 2009.
 
April 19-20: CHI’s Seventeenth Annual Fragment-Based Drug Discovery, the longest-running fragment event, returns in-person to sunny San Diego (and will also be online). This is part of the larger Drug Discovery Chemistry meeting. You can read impressions of the 2021 virtual meeting here, the 2020 virtual meeting here, the 2019 meeting here, the 2018 meeting here, the 2017 meeting here, the 2016 meeting here; the 2015 meeting herehere, and here; the 2014 meeting here and here; the 2013 meeting here and here; the 2012 meeting here; the 2011 meeting here; and 2010 here

May 9-11:  While not exclusively fragment-focused, the Eighth NovAliX Conference on Biophysics in Drug Discovery will have several relevant talks, and for the first time will use a hybrid model, both online and in Munich, Germany. You can read my impressions of the 2018 Boston event here, the 2017 Strasbourg event here, and Teddy's impressions of the 2013 event herehere, and here.
 
October 17-20: CHI’s Twentieth Annual Discovery on Target will be held both virtually and in Boston, as it was last year. As the name implies this event is more target-focused than chemistry-focused, but there are always plenty of FBDD-related talks. You can read my impressions of the 2020 virtual event here, the 2019 event here, and the 2018 event here.
 
Know of anything else? Please leave a comment or drop me a note!

30 December 2021

Review of 2021 reviews

As the year winds down SARS-CoV-2 continues its relentless drive through Greek letters and the planet. But there is hope: vaccines seem to be holding, for those who have access, and two oral drugs have been granted emergency use authorization by the US FDA, one of which (PF-07321332) is covalent and looks remarkably effective. As is our custom, Practical Fragments ends the year by highlighting conferences and reviews.
 
Conferences started the year online only (CHI’s Sixteenth Annual Fragment-based Drug Discovery), moved to hybrid (CHI’s Nineteenth Annual Discovery on Target) and sadly returned to virtual (Pacifichem 2021).
 
This year produced more than twenty FBLD-related reviews, and these are grouped thematically: NMR and crystallography, computational methods, targets, library design, and covalent fragments. The most general is the sixth installment in a series of annual reviews in J. Med. Chem. covering fragment-to-lead success stories from the previous year. Iwan de Esch (Vrije Universiteit Amsterdam) took the lead (pardon the pun) on the most recent review, which details 21 examples from 2020. In addition to the centerpiece table showing fragment, lead, and key parameters, this open-access paper also includes an analysis on the molecular complexity of fragment hits.
 
NMR and crystallography
Consistent with its central role in FBLD, several reviews covered NMR. Ben Davis (Vernalis), one of the leading practitioners, discusses fragment screening in Methods Mol. Biol. The chapter is written for a non-specialist, so you won’t see detailed pulse sequences. Instead, Ben provides a very accessible and practical guide covering everything from sample preparation through data analysis and validation.
 
A more detailed description of solution NMR in drug discovery by Li Shi and Naixia Zhang (Shanghai Institute of Materia and Medica) is published (open access) in Molecules. With 180 references, this review covers considerable ground, including various ligand-detected and protein-detected methods for screening as well as for hit-to-lead and mechanistic studies. The paper also includes a nice summary of in-cell (!) NMR.
 
The Pacifichem meeting had several talks on fluorine NMR, and speaker Will Pomerantz, together with Caroline Buchholz, has published a thorough, open-access review in RSC Chem. Biol. Will has been a leading developer of protein-observed 19F NMR, so naturally this topic is well-covered, but there is plenty on ligand-observed 19F NMR as well as a good background section and musings on the future of the field.
 
And if you’re looking for a detailed how-to guide for NMR-based fragment screening, Harald Schwalbe and colleagues describe the platform they’ve built at the Center for Biomolecular Magnetic Resonance (BMRZ) at Johann Wolfgang Goethe-University Frankfurt in J. Vis. Exp. This open-access paper also describes quality control experiments of the iNEXT library, which we’ve discussed here.
 
Switching gears to crystallography, J. Vis. Exp. carries a paper by Frank von Delft and collaborators describing the XChem platform at the Diamond Light Source. This high-throughput fragment screening platform has delivered a 95% success rate on more than 150 screens, with hit rates varying from 1-30%. In addition to technical details, this open-access article also provides tips on successfully getting your screening proposal through peer review.
 
XChem has inspired similar efforts at other synchrotrons, including the Fast Fragment and Compound Screening (FFCS) platform at the Swiss Light Source. This is concisely described by May Sharpe and Justyna Wojdyla in Nihon Kessho Gakkaishi (open-access and published in English).
 
Private companies are also moving into high-throughput crystallography. Debanu Das and collaborators describe the platform at Accelero Biostructures, which is capable of screening ~500 fragments in two days. Screens against three nucleases are described in some detail in an open-access article in Prog. Biophys. Mol. Biol.; these and other components of the DNA damage response are the focus of XPose Therapeutics, Accelero’s sister company.
 
Computational methods
In addition to the experimental methods reviewed above, a couple papers describe computational approaches. In Drug Disc. Today: Tech., FragNet alum Moira Rachman and collaborators from UCSF, Universitat de Barcelona, and elsewhere focus on “fragment-to-lead tailored in silico design.” This is a nice review of the recent literature and emphasizes the fact that much of the heavy design lifting is still done by medicinal chemists – at least for now.
 
Predicting the energies of modified fragments has long been a challenge, and one promising approach is free energy perturbation, in which one ligand is “perturbed” into another and the relative energy differences calculated. Barbara Zarzycka and colleagues at Vrije Universiteit Amsterdam provide a concise review for aficionados in Drug Disc. Today: Tech.
 
Targets
Three reviews cover applications of FBLD to various target classes. Kinases have been particularly successful, with four of the six approved fragment-derived drugs targeting these enzymes. In Trends Pharm. Sci., Ge-Fei Hao and collaborators, mostly at Central China Normal University, review the state of the art. In addition to background and several case studies, the paper includes a nice table showing structures and summaries of clinical-stage kinase inhibitors.
 
Epigenetics has been another fruitful area, and in J. Med. Chem. Miguel Vaidergorn, Flavio da Silva Emery (both University of São Paulo) and Ganesan (University of East Anglia) detail the “successful union of epigenetic and fragment based drug discovery (EPIDD + FBDD).” This thorough summary (with 165 structures!) of the literature is particularly detailed when it comes to bromodomains, four inhibitors of which have entered the clinic with the help of fragments. The researchers point out that EPIDD and FBDD both began around the same time, and in fact the oncology drug vorinostat could be described as “a unique case of solvent-based drug discovery.”
 
RNA has long been a target of FBLD, and in ChemMedChem Mads Clausen (Technical University of Denmark) and collaborators review the state of the art. The various established and emerging methods to find fragment hits are covered in depth, and there is also a nice discussion as to whether RNA-focused fragment libraries will be useful.
 
Library design and molecular properties
In Expert Opin. Drug Discov. Zenon Konteatis (Agios) asks “what makes a good fragment in fragment-based drug discovery?” His answers provide a concise summary touching on the rule of three, molecular complexity, “three-dimensionality”, and other topics.
 
The topic of three-dimensional fragments is covered in several other reviews. In Drug Disc. Today: Tech., Iwan de Esch and collaborators at Vrije Universiteit Amsterdam and University of York assess 25 so-called 3D libraries reported in the literature, mostly since 2015. The researchers manually drew all 897 fragments so they could calculate various properties. While most of the molecules are rule-of-three compliant, just under half could be called 3D by both plane of best fit (PBF) and principal moment of inertia (PMI). PBF and PMI measurements correlated with one another, while Fsp3 correlated with neither measurement, leading to the conclusion that “Fsp3 is a poor measure of 3D shape.”
 
Shapely or not, sp3-rich fragments are interesting from a diversity point of view, and in Chem. Sci. Max Caplin and Dan Foley (University of Canterbury) discuss synthetic methods for advancing these. This is an excellent open-access review of the recent literature around C-H bond functionalization and well worth reading for the chemists in the audience.
 
3D fragments are often chiral, and the importance of chirality in drug discovery is the focus of a paper in ACS Med. Chem. Lett. by Ilaria Silvestri and Paul Colbon (University of Liverpool). The researchers note an opportunity for chemical suppliers: only 245 of 9751 heterocyclic building blocks offered by Sigma-Aldrich are chirally pure.
 
“Library design strategies to accelerate fragment-based drug discovery” is the topic of a Chem. Eur. J. review by Nikolaj Troelsen and Mads Clausen (Technical University of Denmark). The researchers provide a highly accessible overview of different libraries appropriate for different fragment-finding methods, including covalent approaches.
 
Covalent fragments
This year saw the approval of sotorasib, the first covalent fragment-derived drug, so it is no surprise that several papers focus on this topic. Sara Buhrlage, Jarrod Marto, and colleagues at Dana-Farber Cancer Institute provide a thorough introduction to “chemoproteomic methods for covalent drug discovery” in Chem. Soc. Rev. The review covers both isolated protein screening as well as proteome-wide methods and includes multiple case studies.
 
Nir London and colleagues at The Weizmann Institute of Science focus on “covalent fragment screening” in Ann. Rep. Med. Chem. This is an excellent review of the recent literature and also includes an analysis of six commercial covalent fragment libraries.
 
And finally, in RSC Chem. Biol. (open access), Nathanael Gray and collaborators mostly at Dana-Farber Cancer Institute discuss strategies for “fragment-based covalent ligand discovery”, including computer-aided approaches, as well as target classes and new modalities such as PROTACs. They end by asking whether sotorasib was “a lucky, one-off case” or “a preview of continued and increased impacts that these approaches will have on drug discovery as the improved methods, larger libraries, and increased focus start to bear fruit.”
 
I’m betting on the latter.
 
And that’s it for 2021. Thanks for reading, special thanks for commenting, and here’s hoping we’ll be able to meet in person in 2022.

22 December 2021

Pacifichem 2021

Pacifichem, the last significant conference of 2021, has just ended. Traditionally held every five years, these meetings usually bring thousands of visitors from Pacific Rim countries to Honolulu. They are planned years in advance: symposia proposals were due in early 2018. Pacifichem 2015 saw the first symposium dedicated to FBLD, and that was so popular that a few of us planned one for 2020. The conference organizers decided to postpone the 2020 meeting in the hope that we could all meet in person. But SARS-CoV-2 had other plans, and instead of meeting in Hawaii we met on Zoom.
 
Time zones were challenging. Four-hour sessions started in the morning or evening Hawaiian time, which translated to 02:00 in Shanghai or 23:00 in Boston, respectively. In contrast to other virtual meetings almost all the presentations were live and not recorded, which meant that you only had one chance to see a talk.
 
Despite these challenges and universal Zoom-fatigue, the event came off quite well. With more than two dozen presentations I won’t attempt to cover everything but will instead just touch on a few themes.
 
Methods
Quite a few talks focused on methods, with NMR being especially well-represented. The symposium started with Will Pomerantz (University of Minnesota) discussing Protein-Observed Fluorine (PrOF) NMR, in which fluorinated amino acids are introduced into proteins. We’ve written about this previously, including Will’s longstanding interest in assessing shapely fragments. After reading about Mads Clausen’s fluorinated Fsp3-rich library, Will established a collaboration and has found 8 hits from 79 fragments screened against BET bromodomain proteins. He has also been able to optimize potent leads selective for either the BD1 or BD2 domains of BRD4.
 
Scott Prosser (University of Toronto) is also using NMR to study fluorine-labeled proteins, in this case GPCRs. And Michael Overduin (University of Alberta), one of the symposium organizers, is also studying membrane-bound proteins using NMR techniques.
 
On the extreme side of spectrometers, Chojiro Kojima described the 950 MHz NMR at Osaka University. This enables a 1H-13C HSQC experiment on protein as dilute as 0.2 micromolar, which could be valuable for insoluble or hard-to-purify proteins. The facility is open to international collaborators. Chojiro also described isotopically labeling proteins with transglutaminase and 1H{19F} STD NMR, which works even when the fluorine peak itself is broadened to invisibility.
 
But you don’t need a big magnet to do good science. Brian Stockman’s group at Adelphi University is composed entirely of undergraduates who use substrate-detected NMR to follow enzymatic reactions to find inhibitors of neglected parasitic infections.
 
All techniques can give false positives, and NMR can be very effective at weeding these out. As we described two years ago Steven LaPlante (NMX) has been developing methods to rapidly identify aggregators and has been assembling something of a taxonomy; more later.
 
But the conference was not all NMR all the time. Rebecca Whitehouse (Monash University) described a 91-compound “MicroFrag” library consisting of fragments containing 5-8 atoms, “somewhere in the land between solvents and fragments.” NMR and crystallographic screens of the difficult antimicrobial target DsbA gave very high hit rates, and both techniques successfully identified the large but shallow substrate-binding groove. In contrast, screening actual solvents or using the well-established FTMap computational approach did not clearly identify this groove.
 
The push in crystallography is towards increased speed, and Debanu Das described the high-throughput platform at Acclero BioStructures, which is capable of screening 1000 fragments per week, similar to XChem. But if even that is too slow for you, Marius Schmidt (University of Wisconsin-Madison) described mix-and-inject experiments using the European X-ray free-electron laser (XFEL). Much of the focus with this technique has been on high-speed enzymology, but since 100 datasets can be collected in 10 hours it can be used for high-throughput crystallographic screening too. An upgrade next year will increase this to 1000 datasets in 3 hours, though the resulting petabytes of data will no doubt create headaches for IT departments.
 
It’s not enough to find hits, you need to figure out what to do with them, and symposium organizer Martin Scanlon (Monash University) discussed a computational approach (GRADe, similar to Fragment Network) as well as the experimental (REFiL) approach we’ve discussed previously. Across 9 projects the techniques were successful at improving affinity, in some cases from unmeasurable levels.
 
Covalent Fragments
Several talks focused on covalent FBLD. Alexander Statsyuk (University of Houston) proposed five rules for covalent fragments: 1) ease of synthesis; 2) non-promiscuous electrophiles; 3) intrinsic reactivity should be the same within the library; 4) a given library should use the same electrophile; and 5) the electrophile should be on the end of the molecule with a minimal linker connecting it to the variable fragment. Some of these make sense, but it would have been fun to debate others over Mai Tais.
 
Dan Nomura (UC Berkeley) described using covalent fragments in chemoproteomic experiments, where he has identified more than 100,000 potentially ligandable hotspots in more than 16,000 human proteins. Among other applications, this allows him to make bifunctional molecules to bring two proteins together. A clear application is PROTACs, where the electrophilic fragment targets an E3 ligase, but he also described targeting the deubiquitinase OTUB1 to stabilize proteins.
 
Earlier this year we celebrated the approval of the KRASG12C inhibitor sotorasib. This target had long resisted drug discovery efforts; Ratmir Derda (University of Alberta) evocatively mentioned “waves and waves of medicinal chemists washing off its shore for 30 years.” Success was finally enabled using disulfide Tethering, and David Turner (Frederick National Laboratory) is now using this approach to interrogate nearly every surface-exposed residue by systematically mutating them to cysteines and screening against more than 1000 disulfide-containing fragments. He is well over half-way through the 85 mutants, and the resulting dataset should be valuable not just for drug discovery but for understanding molecular interactions.
 
Success Stories
With more than 50 drugs in the clinic derived from fragments, there were several success stories. Masakazu Atobe (Asahi Kasei) presented the discovery of the potent PKCζ inhibitors we wrote about here. And Chaohong Sun (AbbVie) described inhibitors of TNFα (see here), emphasizing the importance of robust biophysics and early committed chemistry.
 
Finally, Emiliano Tamanini (Astex) presented a nice fragment-to-lead effort to find a selective inhibitor of HDAC2. Despite some successes, histone deacetylase inhibitors tend to be non-specific and come with side effects. Emiliano described a fragment screen that identified a new metal chelator and used fragment merging to develop a molecule capable of crossing the blood-brain-barrier.
 
These last two stories in particular are examples of pursuing difficult targets, another theme throughout the conference. When asked about the challenges of targeting cancer-resistance-causing glucuronosyltransferases, Katherine Borden (University of Montreal) responded, “if you don’t try, where will you be?”
 
Bright words for these darkling days.